Protocol Buffers in Go
Protocol Buffers in Go
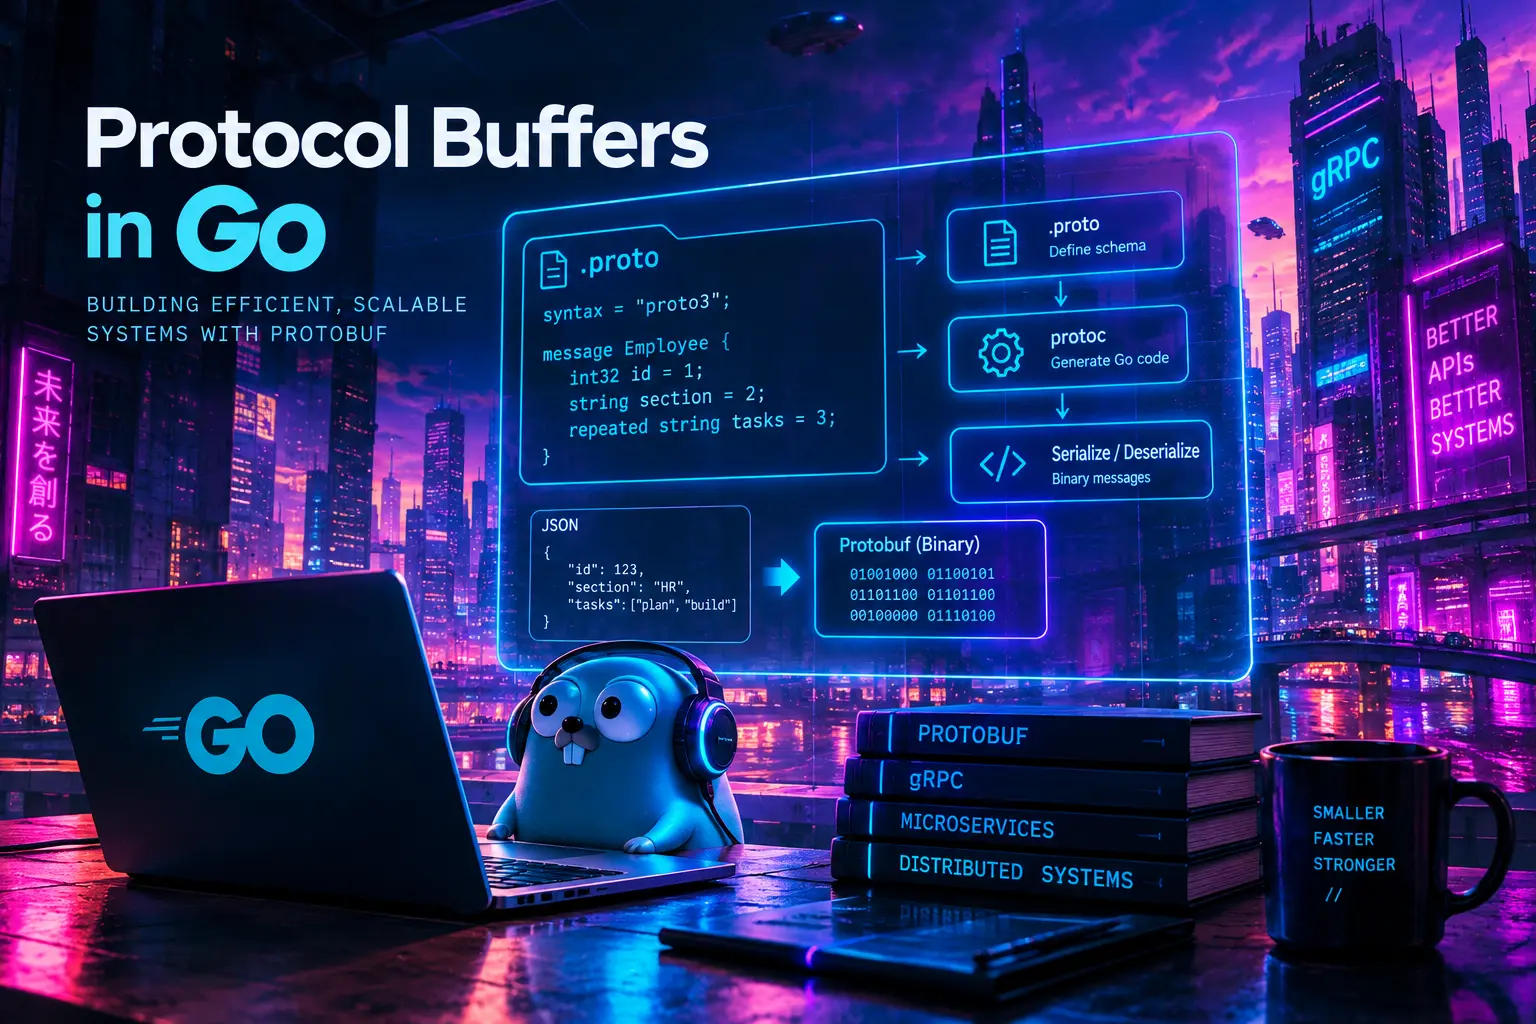
Protocol Buffers (protobuf) is a language-neutral mechanism for serializing structured data. Used in distributed systems, APIs, and microservice architectures where efficient communication between services is important.
Protobuf serializes data into a compact binary representation. This makes messages smaller and generally faster to serialize, transmit, and deserialize.
Protobuf is used with gRPC, where it is used as the default interface definition and serialization format.
What Are Protocol Buffers?
Protocol Buffers provide a structured way of defining and exchanging data between different applications and services.
Instead of defining the structure of data separately in each programming language, you create a .proto file that acts as a shared schema.
For example:
syntax = "proto3";

message Employee {
  int32 id = 1;
  string section = 2;
  repeated string tasks = 3;
}
This schema defines a Employee message with 3 fields:
- An
idinteger - A
sectionstring - A list of
tasks
The .proto file becomes the contract between the systems that consume the data.
Schema Definition
The structure of Protobuf messages is defined using Protobuf's Interface Definition Language (IDL).
The schema describes:
- Message types
- Field names
- Field types
- Field numbers
- Repeated fields
- Enums
- Services
This gives distributed systems a clear and strongly defined data contract.
Binary Serialization
When a Protobuf message is serialized, it is converted into a compact binary format.
For example, a JSON representation might look conceptually like this:
{
  "id": 26,
  "section": "HR"
}
Protobuf instead encodes the same information into binary data.
The binary representation is not intended to be human-readable, but it is compact and efficient for machines to process.
Language Support
One of the biggest advantages of Protobuf is that the same .proto schema can be used across multiple programming languages.
Generated code is available for languages such as:
- Go
- C++
- Java
- Python
- C#
- JavaScript and TypeScript
This makes Protobuf particularly useful when different services are implemented using different languages.
Backward and Forward Compatibility
Protobuf schemas are designed to evolve over time.
New fields can be added without necessarily breaking clients that still use an older version of the schema.
This is important in distributed systems where updating every service simultaneously is often a problem.
Key Features of Protocol Buffers
There are three characteristics that make Protobuf particularly useful in distributed systems.
Efficiency
Protobuf messages use a compact binary representation.
Compared with text-based formats such as JSON or XML, this can reduce message size and the amount of data transmitted over a network.
It can also provide faster serialization and deserialization.
Cross-Platform Communication
The same Protobuf schema can be used by services written in completely different programming languages.
For example:
Go Service
    |
    | Protobuf
    v
Node.js Service
or:
Go Service
    |
    | Protobuf
    v
Python Service
The services don't need to share the same programming language. They only need to agree on the Protobuf contract.
Schema-Driven Development
Protobuf is schema-driven.
The .proto file defines the expected structure of the data, providing a clear contract between applications and services.
This is particularly useful in larger systems where many services need to communicate reliably.
How Protocol Buffers Work
The basic Protobuf workflow consists of four stages:
- Define a
.protoschema - Generate code
- Serialize a message
- Deserialize the message
Let's go through each step using Go.
1. Define a .proto file
The first step is to define the data structure.
For example:
syntax = "proto3";

package example;

option go_package = "github.com/georgecrisan/protobuf-go-example/pb";

message Employee {
  int32 id = 1;
  string section = 2;
  repeated string tasks = 3;
}
The numbers assigned to the fields are called field numbers or tags.
For example:
int32 id = 1;
string section = 2;
repeated string tasks = 3;
These numbers become part of the serialized representation and are important when maintaining compatibility between different versions of a schema.
2. Compile the .proto file
Once the schema has been created, the Protobuf compiler can generate Go code from it.
For example:
protoc \
  --go_out=. \
  --go_opt=paths=source_relative \
  employee.proto
If the schema also defines gRPC services, you can generate the gRPC-specific Go code as well:
protoc \
  --go_out=. \
  --go_opt=paths=source_relative \
  --go-grpc_out=. \
  --go-grpc_opt=paths=source_relative \
  employee.proto
The generated Go files contain the structures and methods needed to work with the messages.
Instead of manually writing serialization and deserialization logic, your application uses the generated code.
3. Serialize data in Go
After generating the Go code, you can create a Employee message.
For example:
package main

import (
	"fmt"
	"log"
	"google.golang.org/protobuf/proto"
	"github.com/georgecrisan/protobuf-go-example/pb"
)

func main() {
	employee := &pb.Employee{
    Id:   26,
		Section: "HR",
		Tasks: []string{
			"admin",
      "payroll"
		},
	}

	serializedData, err := proto.Marshal(employee)
	if err != nil {
		log.Fatal(err)
	}

	fmt.Printf("Serialized data: %x\n", serializedData)
}
The important operation here is:
serializedData, err := proto.Marshal(employee)
proto.Marshal converts the Go Protobuf message into its binary representation.
The resulting []byte can then be transmitted over a network or stored somewhere such as a database or cache.
Conceptually, the process looks like this:
Go struct
   |
   | proto.Marshal()
   v
[]byte
   |
   | Network / Storage
   v
Binary Protobuf message
4. Deserialize Data in Go
When another service receives the serialized bytes, it can reconstruct the original Protobuf message.
For example:
package main

import (
	"fmt"
	"log"
	"google.golang.org/protobuf/proto"
	"github.com/georgecrisan/protobuf-go-example/pb"
)

func main() {
	// Assume serializedData was received from a network
	// or retrieved from storage.
	var serializedData []byte

	employee := &pb.Employee{}

	err := proto.Unmarshal(serializedData, employee)
	if err != nil {
		log.Fatal(err)
	}

	fmt.Println("Section:", employee.GetSection())
	fmt.Println("ID:", employee.GetId())

	for _, task := range employee.GetTasks() {
		fmt.Println("Tasks:", task)
	}
}
The key operation is:
proto.Unmarshal(serializedData, employee)
This takes the binary representation and populates the generated Go structure.
The application can then work with the message as normal Go data.
Protocol Buffers in System Architecture
Protobuf becomes particularly interesting when we move beyond individual applications and look at distributed systems.
A typical architecture might contain multiple services communicating with one another:
             ┌──────────────┐
             │   Client     │
             └──────┬───────┘
                    │
                    ▼
             ┌──────────────┐
             │ API / Service│
             └──────┬───────┘
                    │
              Protobuf / gRPC
                    │
                    ▼
             ┌──────────────┐
             │ User Service │
             └──────┬───────┘
                    │
                    ▼
             ┌──────────────┐
             │   Database   │
             └──────────────┘
The .proto file can become the shared contract used by these components.
1. Define Protobuf Messages
Start by defining the messages used by your system.
For example:
syntax = "proto3";

package example;

option go_package = "github.com/georgecrisan/protobuf-go-example/pb";

message Employee {
  int32 id = 1;
  string section = 2;
  repeated string tasks = 3;
}
The schema becomes the source of truth for the structure of the message.
2. Generate Go Code
The .proto file is then compiled into Go code.
For example:
protoc \
  --go_out=. \
  --go_opt=paths=source_relative \
  employee.proto
The generated code provides the Go structures required to serialize and deserialize the messages.
If you're using gRPC, generated client and server interfaces can also be produced.
3. Communication Protocols: gRPC
One of the most common applications of Protobuf is gRPC.
With gRPC, you can define both the messages and the RPC service in the same .proto file.
For example:
syntax = "proto3";

package example;

option go_package = "github.com/georgecrisan/protobuf-go-example/pb";

service EmployeeService {
  rpc GetEmployee(EmployeeRequest) returns (EmployeeResponse);
}

message EmployeeRequest {
  int32 id = 1;
  string section = 2;
}

message EmployeeResponse {
  int32 id = 1;
  string section = 2;
  repeated string tasks = 3;
}
This defines an RPC method:
GetEmployee()
which accepts a EmployeeRequest and returns a EmployeeResponse.
The Protobuf compiler can then generate the Go interfaces required to implement both sides of the communication.
Implementing a gRPC Server in Go
A simplified Go server might look like this:
type server struct {
	pb.UnimplementedEmployeeServiceServer
}

func (s *server) GetEmployee(
	ctx context.Context,
	req *pb.EmployeeRequest,
) (*pb.EmployeeResponse, error) {

	return &pb.EmployeeResponse{
    Id:  req.GetId(),
    Section:  req.GetSection(),
    Tasks: []string{"payroll", "admin"},
	}, nil
}
The generated interface ensures that the implementation follows the contract defined in the .proto file.
The client does not need to know how the server internally retrieves the data.
It calls the RPC:
Client
   |
   | GetEmployee(request)
   v
gRPC Server
   |
   | response
   v
Client
Underneath the RPC call, Protobuf is responsible for encoding and decoding the messages.
Protobuf for Data Storage
Protobuf is not limited to network communication. A serialized protobuf message can be stored in a database or cache.
For example:
employee := &pb.Employee{
  Id: 26,
	Section: "HR",
	Tasks: []string{
		"payroll",
    "admin"
	},
}

serializedData, err := proto.Marshal(employee)
if err != nil {
	log.Fatal(err)
}
The resulting serializedData is a byte slice that can be stored as binary data.
When the data is retrieved, it can be reconstructed:
employee := &pb.Employee{}

err := proto.Unmarshal(serializedData, employee)
if err != nil {
	log.Fatal(err)
}

fmt.Println(employee.GetSection())
fmt.Println(employee.GetId())

for _, tasks := range employee.GetTasks() {
	fmt.Println(tasks)
}
This approach can be useful when compact serialized representations are desirable.
Protobuf for Inter-Service Communication
In a microservice architecture, services frequently need to exchange structured messages.
For example:
┌──────────────┐
│ Order Service│
└──────┬───────┘
       │
       │ Protobuf
       ▼
┌──────────────┐
│Payment Service│
└──────┬───────┘
       │
       │ Protobuf
       ▼
┌──────────────┐
│Notification  │
│   Service    │
└──────────────┘
Each service can use the same .proto definitions.
This provides a common contract while allowing the individual services to remain independently implemented.
For example, a Go client generated from a gRPC service can create a request like this:
request := &pb.EmployeeRequest{
  Id:   26,
	Section: "HR"
}

response, err := client.GetEmployee(ctx, request)
if err != nil {
	log.Fatal(err)
}

fmt.Println("Received:", response)
The application developer doesn't need to manually construct a JSON payload or parse a JSON response.
The generated client handles the communication according to the Protobuf and gRPC contract.
Why Use Protobuf?
There are several reasons Protobuf is popular in distributed systems.
1. Efficiency
Binary messages are compact and efficient to serialize and deserialize.
This can reduce network bandwidth and improve communication performance.
2. Compatibility
Protobuf schemas can evolve while maintaining compatibility with older clients and services, provided the schema changes follow Protobuf's compatibility rules.
This is particularly valuable in large distributed systems where services are deployed independently.
3. Language Neutrality
A single .proto definition can generate code for multiple programming languages.
For example:
             employee.proto
                  │
       ┌──────────┼──────────┐
       ▼          ▼          ▼
      Go        Java       Python
This makes it possible for services written in different languages to communicate using the same contract.
4. Structured Data
The schema provides a clearly defined structure for messages.
Instead of relying on loosely structured data, developers can see exactly what fields are expected and what types they have.
5. Performance
Protobuf is designed for efficient serialization and deserialization and is generally more compact than text-based formats such as JSON and XML.
Performance Considerations
When working with Protobuf in high-throughput systems, there are several areas worth considering.
Use proto3
The proto3 syntax is commonly used for modern Protobuf applications and provides a simpler schema definition model.
For example:
syntax = "proto3";
It is designed with simplicity, interoperability, and efficient encoding in mind.
Field Numbers
Every field has a numeric tag:
int32 id = 1;
string section = 2;
repeated string tasks = 3;
These field numbers are part of the wire format.
Once a field number has been used in a production schema, it should generally not be reused for a different field.
Avoid Unnecessary Complexity
Deeply nested messages can make schemas harder to understand and maintain. Nesting itself is not necessarily a performance problem, so message structure should primarily be designed around the domain and API contract rather than prematurely optimizing serialization.
Where appropriate, keeping message structures straightforward can make systems easier to maintain.
Reuse Objects Where Appropriate
In high-throughput applications, repeated allocations can contribute to memory pressure and garbage-collection overhead.
Where profiling shows this to be a problem, carefully designed object reuse or pooling strategies can help.
This should be driven by measurement rather than applied everywhere by default.
Batch Operations
If an application needs to process large numbers of messages, batching operations can reduce repeated processing overhead and potentially improve throughput.
Advanced Protobuf Features
Protobuf supports more than simple strings and integers.
Nested Messages
Messages can contain other messages:
message Address {
  string city = 1;
  string country = 2;
}

message Employee {
  int32 id = 1;
  Address address = 2;
}
Repeated Fields
Repeated fields can represent lists:
message Employee {
  repeated string tasks = 3;
}
The generated Go code exposes this as a slice:
employee := &pb.Employee{
	Tasks: []string{
		"payroll",
		"admin",
	},
}
Enums
Protobuf also supports enumerations:
enum Status {
  STATUS_SPIKED = 1;
  STATUS_ACTIVE = 2;
  STATUS_INACTIVE = 3;
}
Enums are useful when a field should only contain one of a predefined set of values.
Default Values
Protobuf also defines default behavior for fields that aren't explicitly populated.
Understanding these defaults is important when designing schemas and evolving them over time.
Common Use Cases for Protocol Buffers
Protobuf can be used in several areas of modern software architecture.
Network Communication
Protobuf provides an efficient format for exchanging structured data between applications and services.
gRPC
gRPC uses Protobuf as its default message format and interface definition mechanism.
This makes Protobuf a natural choice for service-to-service communication.
Microservices
Microservices can share Protobuf contracts while remaining independently implemented and deployed.
Data Storage
Serialized Protobuf messages can be stored as binary data in databases, caches, or other storage systems where that representation is appropriate.
Configuration
Protobuf can also be used to define structured configuration data where schema validation and strongly defined structures are useful.
Protocol Buffers provide more than just an alternative to JSON.
They provide a schema-driven contract between applications and services, combined with compact binary serialization and support for multiple programming languages.
For Go developers, Protobuf becomes especially powerful when combined with gRPC.
A typical workflow looks like this:
        Define .proto
             │
             ▼
       Run protoc
             │
             ▼
     Generate Go code
             │
       ┌─────┴─────┐
       ▼           ▼
    Client       Server
       │           │
       └─────┬─────┘
             │
          gRPC
             │
         Protobuf
             │
             ▼
      Binary messages
The .proto file defines the contract, the generated Go code provides the implementation primitives, and Protobuf handles the serialization layer.
This combination makes Protobuf particularly well suited to distributed systems, microservices, and high-performance service-to-service communication.